Product
Spend is capped before it happens.
Brigham.ai checks the budget before each model call, not after the invoice. Every run shows tokens and dollars.
Limits that live in code.
Per runToken and time caps
Per daySpend cap for each workspace
BeforeChecked ahead of every model call
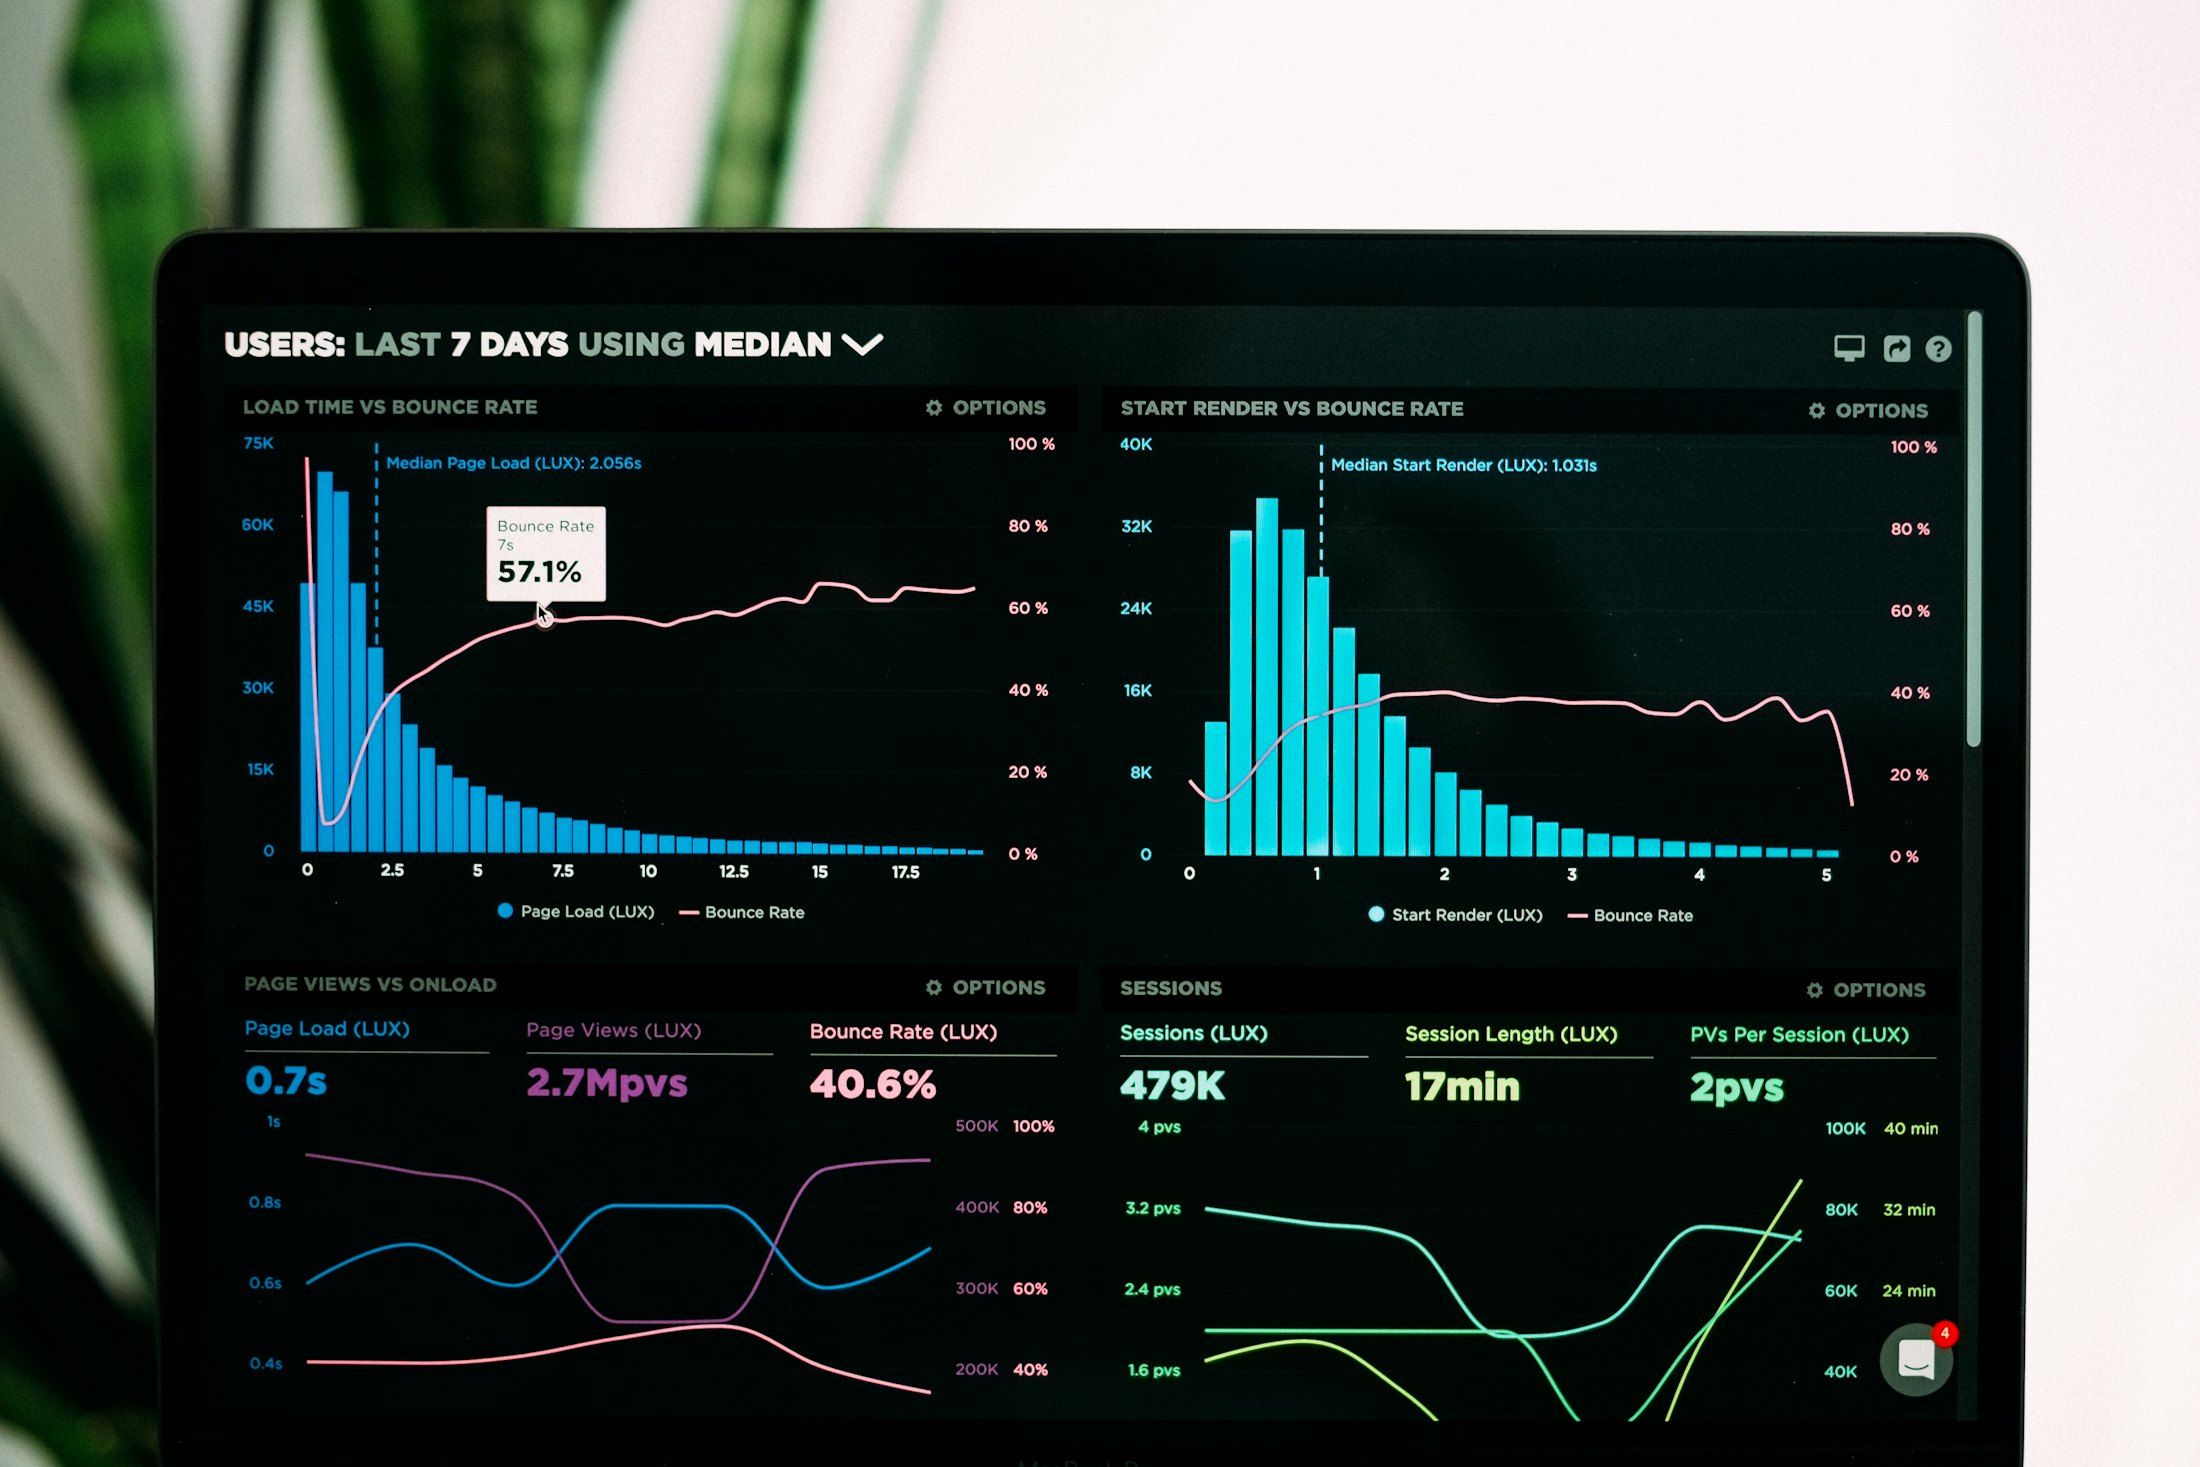
Every run shows its bill.
Usage events record input and output tokens, cache reads and cache writes, and the cost in US dollars. You can see which task spent what.
- Cache read and write tokens counted.
- USD per run and per workspace.
- Usage reported to billing.
Cheaper by design.
01
Three model tiers
Fast, standard and deep. Brigham.ai picks the smallest that will do the job.
02
Prompt caching
Stable context is cached, so repeated work costs less.
03
Code before inference
Math, filters and lookups run as deterministic code, not tokens.
A runaway loop hits a wall, not your budget.
Questions, answered.
What happens at the cap?
The run stops and says why. It does not quietly continue.
Can automations have their own cap?
Yes. Each automation carries its own cost ceiling.
Keep reading.
AutomationsRun Brigham.ai on a schedule or when something happens. Cron with time zones, event triggers, workflows that pause for approval, and a cost cap on each.Read →
Audit trailEvery Brigham.ai tool call passes eight stages and is logged with redacted arguments. Searchable. Finance-labelled rows stay hidden from non-grantees.Read →
Specialist agentsSales, Marketing, Dev, Finance, Ops and Research agents the chief of staff delegates to. Delegation never widens permissions.Read →
AI with a spending limit.
Get started today.